❯ ingest --source "likhith v" --tokenizer bpe --chunk semantic

{{ t.text }}{{ t.id }}

{{ t.text }}{{ t.id }}{{ t.text }}{{ t.id }}

AI Engineer at Networth Corp, Bengaluru. Two years of production AI: systems that let a company ask questions of its own documents and get answers it can trust, and that stay accurate and cheap as those documents change.

chunktokenshashstatus
{{ r.id }}{{ r.n }}{{ r.hash }}{{ r.status }}
{{ heroStatus }} ↻ re-ingest
[01]diffincremental data infrastructure · 2026

DeltaVec

A search index for AI has to be rebuilt whenever the source documents change. DeltaVec rebuilds only the parts that actually changed, and never loses track of what was deleted.

live policy.pdf · 5 chunks · click any paragraph to edit it
doc:{{ r.i }}
{{ r.k }}
{{ r.text }}
{{ r.hash }}
{{ r.tag }}
{{ savedPct }}%
of embedding work skipped so far
{{ dvSummary }}
full rebuild each run{{ naive }} calls
deltavec{{ delta }} calls
{{ l.t }}{{ l.s }}
problem

A vector store is a derived dataset. Tutorials embed a static corpus once; production sources mutate constantly. Inserts are trivial. Updates and deletes are where naive pipelines silently break, serving answers from text that no longer exists.

approach

Watermark change detection over a mutating Postgres source, SHA-256 content-hash diffing per chunk, and deterministic chunk IDs (uuid5(ns, "doc:index")) that make every load idempotent. Orphan deletion, tombstones for soft deletes, and a reconciliation sweep for hard deletes. Orchestrated with Dagster behind blocking quality gates; served over FastAPI in Docker.

result

A re-run with no source changes processes nothing and duplicates nothing. Editing one paragraph re-processes one chunk, not the corpus. Six demo scenarios each prove one failure mode is handled, pinned by integration tests against real Postgres and real Qdrant.

decisions I'll defend in an interview · 4 passed
✓ qdrant_not_faiss
Every operation here is a mutation. FAISS is a library tuned for a static index; upsert and filtered delete are first-class in a store, and caller-supplied point IDs are what make the load idempotent.
✓ vectors_and_bookkeeping_split
Qdrant owns vectors, Postgres owns the chunk registry, so change detection is an indexed lookup and reconciliation is a SQL join. Qdrant first, registry second: never record work as done before it is done.
✓ chunk_size_is_schema
Boundaries must be deterministic or every hash changes and the pipeline degrades into a full re-embed that still looks healthy. Chunk size and overlap are versioned, not tuned.
✓ checks_never_repair
Quality gates detect; a separate sweep repairs. A check that quietly fixes what it finds can never tell you your pipeline is broken.
Open the live showcase ↗ Source ↗
[02]retrieveon-device document intelligence · shipped 2026

Anvit

An app that answers questions about your own PDFs (a contract, a report, a medical letter) without uploading them anywhere. The model runs on the phone itself.

problem

Document Q&A normally means sending the document to somebody else's server. For contracts, medical records and financial statements, that is exactly why people don't use it.

approach

A Kotlin Multiplatform app for Android and iOS running Gemma 4 locally through LiteRT-LM. Custom PDF and DOCX parsing with hierarchical chunking along sections, tables and lists, so each piece is a complete unit of content. On top, an agentic retrieval loop: query routing and decomposition, corrective relevance checks, native tool calling and self-critique.

result

Published on Google Play with collections, chat sessions, streaming responses, citations pointing back to the exact passage, and settings-driven model configuration.
constraints that shaped it
01A phone-sized model has no headroom for sloppy retrieval, so the quality of the document splitting does work a bigger model would otherwise absorb.
02There is no server to wait on, so the delay is the phone's own. Every extra reasoning pass has to earn itself.
03Citations are non-negotiable: privacy is the pitch, and an answer about your own contract that you can't verify is worthless.
device boundary
nothing leaves the phone
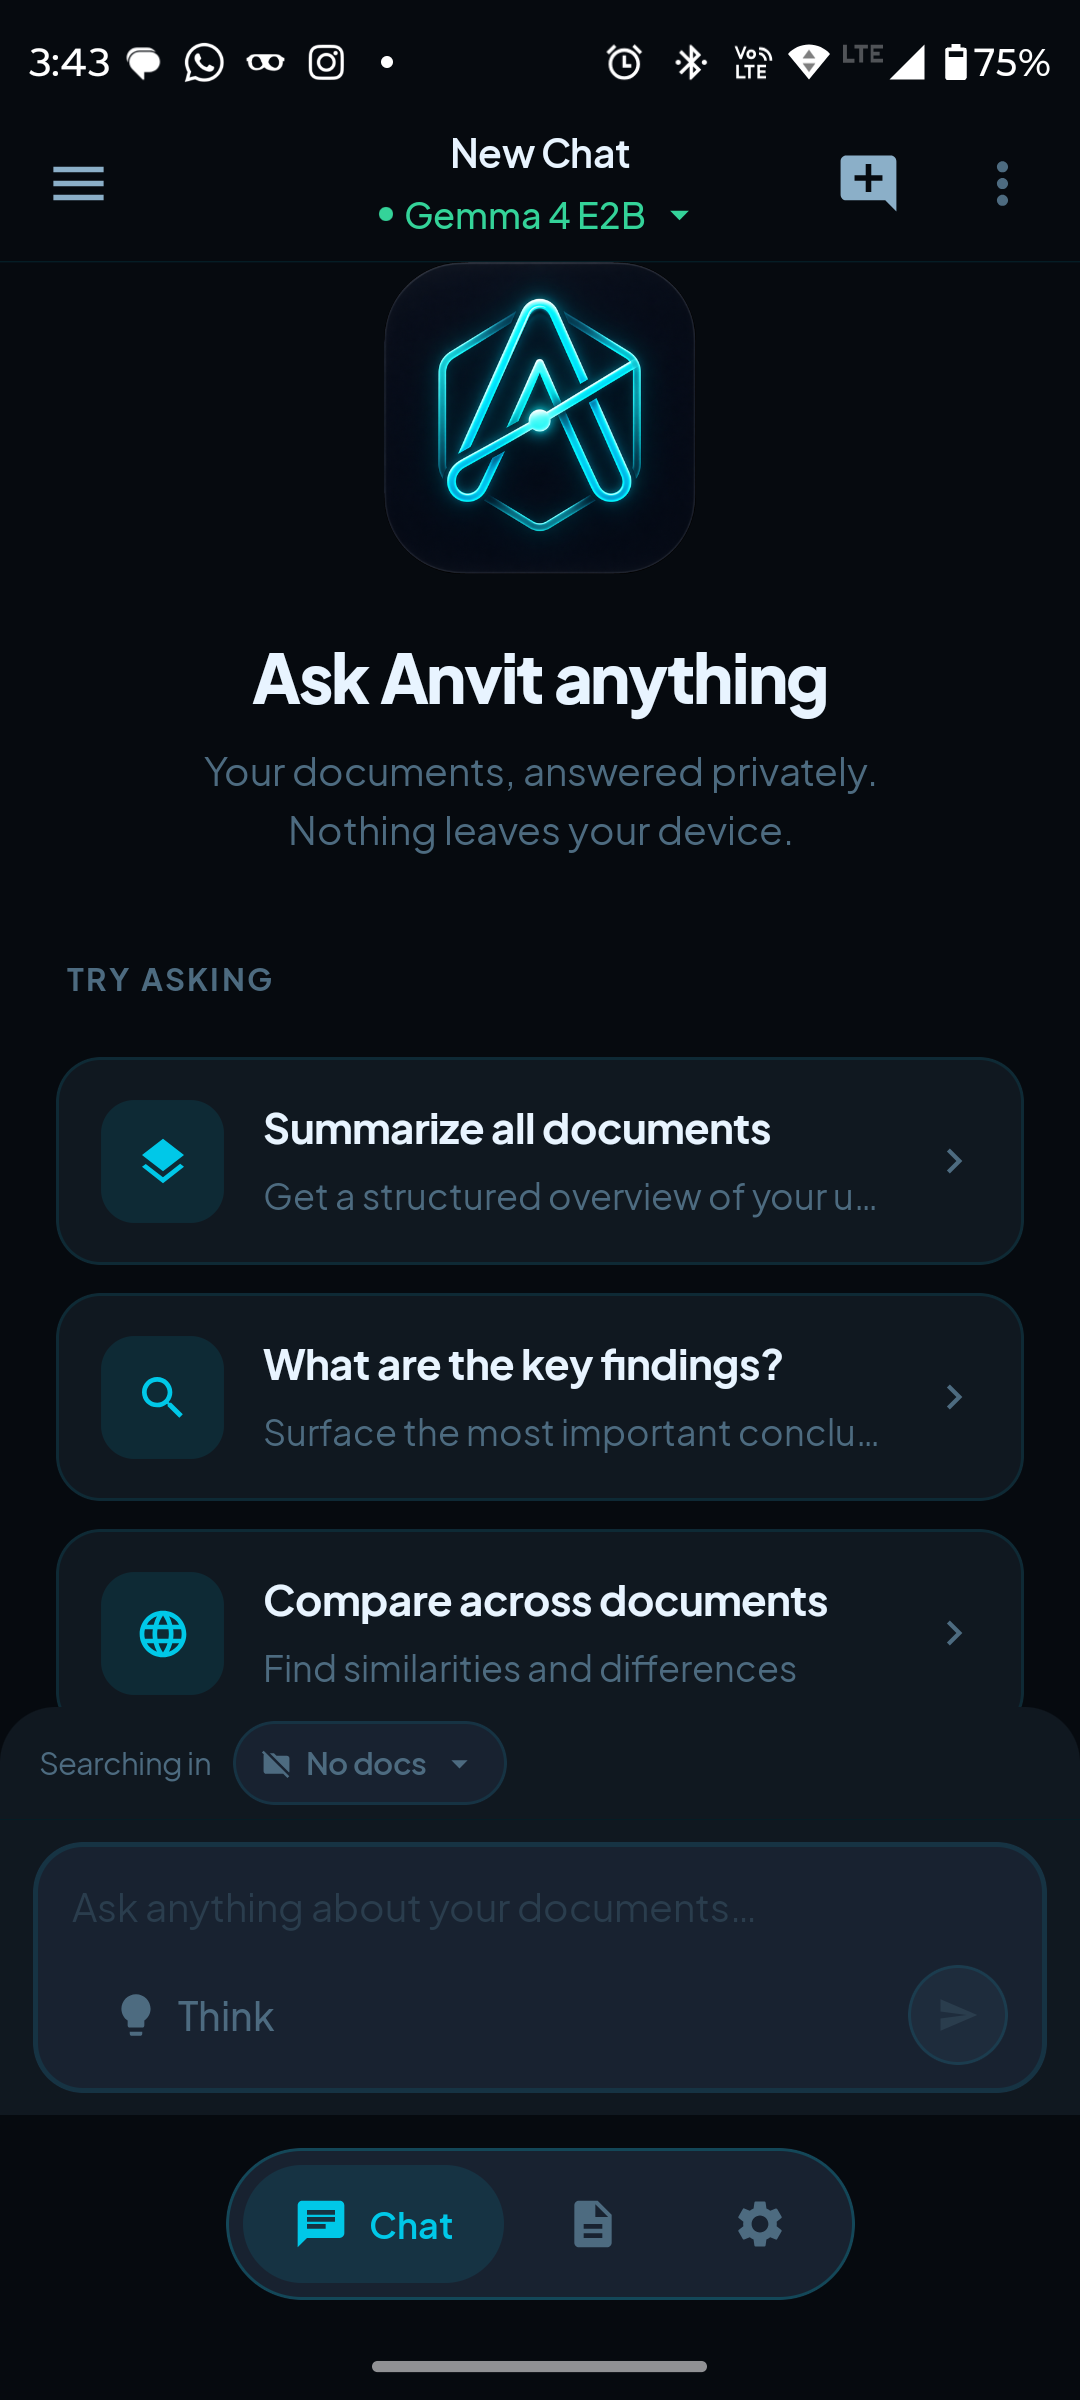
Anvit app home screen running Gemma 4 E2B
01PDF / DOCX
02Structured chunks
03Local retrieval
04Gemma 4 on device
05Cited answer
Kotlin Multiplatform
Gemma 4 · LiteRT-LM
[03]gateagents · 2026

Customer-Support Agent

An AI assistant that handles refund requests but cannot be sweet-talked into approving one. The conversation is the model's job. The decision about money is ordinary code following company policy.

how the agent worksrequest path
SSEtool callsFOR UPDATEChat UI + consoleReact · CloudflareFastAPIJWT · SSE · Cloud RunLangGraph agentReAct tool loopLLM (Gemini 3.8)provider-agnostic · fallbackTools + policy enginedeterministic gatePostgresrow locks · unique indexRedislimits · locks · pub/sub
the numbers full results in the case study ↗
100%
money-safe and policy-correct across 83 golden conversations, graded on every PR
0.98+
tone rated by an LLM judge on Gemini 3.8 Flash and GPT-5.6
0 / 120
AI-written red-team attacks that moved money or leaked data
0
failed requests out of 131,272 in a 2,500-user load spike
problem

An agent that can approve refunds is an agent that can be talked into approving refunds. Money movement cannot depend on a model holding the line under pressure.

approach

The model only talks and calls tools. Money moves through issue_refund, which re-runs the policy engine and locks the order row. Identity comes from a signed JWT, never from the chat.

result

A manipulative message can change the wording of a reply, never what gets paid out. That held across the evals, the red team and the load spike.

Try the live demo ↗ Case study ↗ Source ↗ FastAPI · LangGraph · React · Postgres · Redis · Opik · promptfoo · Kubernetes · Locust
[04]routeagent fleet on a personal vps

Hermes

Five agent workflows on one VPS. Each enters from its own Discord channel and runs through its own gateway, so the workflows stay apart by construction.

select a lane to trace a request {{ hermesCounter }}
{{ l.entry }}
{{ n.label }}
{{ hermesName }}
{{ hermesMission }}
{{ hermesNote }}
Architecture from the VPS documentation. No live connection to the gateways.
[05]renderai video studio

Studio

An agent researches and pitches. I approve. The pipeline scripts, narrates, animates and audits the render. Publishing stays a human decision.

00:00
00:02
00:04
00:06
00:08
00:10
00:12
{{ c.n }}
{{ c.name }}
{{ c.art }}
◆ human
{{ studioDesc }}
output → {{ studioArt }}
Git Merge vs Rebase, Explained in 50s
▶
0:48 · shortclick to play
shipped from this pipeline

Git Merge vs Rebase, Explained in 50s

Merge ties two lines of history together with a new commit; rebase replays your work on top of main. Researched, scripted, narrated, animated and render-checked through the stages above.

2.5k views on Instagram
YouTube channel ↗ @likhith_explains on Instagram ↗
[06]loggit log --author="likhith"

Experience

commit 4e1c9a7 (HEAD → present)

AI Engineer
Networth Corp

Oct 2024 — Present
+Built a custom document-splitting module for an AI chatbot answering questions over insurance paperwork: 20% more accurate answers, 2% lower running cost.
+Built the evaluation and query-rewriting layers that measure whether the chatbot is finding the right passages, and fix it when it isn't.
+Designed the workflows that make answers point back to a real source passage, which keeps the model from confidently making things up.
~Currently building a synthetic data generator: realistic stand-in datasets that keep the statistical relationships of the real data without exposing it.
commit 9b02f3d

AI/ML Intern
PG-AGI

Dec 2023 — Jun 2024
+Led 6 proofs of concept and 2 production GenAI projects, including HireXtra's AI Recruiter, from requirements through implementation.
+Built AI agents and RAG pipelines with Python, FastAPI, MongoDB, LangChain and LlamaIndex.
commit 1a7d00e (init)

BE, Artificial Intelligence & Machine Learning

Dec 2020 — May 2024 · VTU, Bengaluru
[07]notifynext build

Get the next build first.

I'm building more AI products like Anvit and DeltaVec. Leave your email and I'll write when the next one is ready to try. One email per launch.

{{ subMsg }}